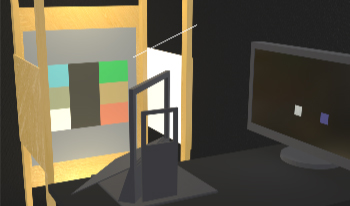
The perceived color in optical see-through augmented reality (AR) deviates from physical additivity, but the driving factors and their interactions remain poorly understood. The authors conducted four psychophysical color-matching experiments manipulating seven factors including stimulus size, viewing mode, starting point, and presentation medium. A generalized linear mixed-effects model analysis of the coordinate-wise differences in CIECAM16-UCS space revealed stimulus size as the strongest predictor. Reducing the stimulus size—which increases the relative area of the chromatic surround—produced shifts that tended to be opposite to the background chromaticity, consistent with classical simultaneous contrast. The viewing mode and presentation medium had small effects concentrated on the blue–yellow axis, whereas the starting point produced a small procedural shift across all axes. The linear additive model showed limitations: nonlinear deviations were confined to specific targets where chromatic induction was strongest. These findings suggest that background discounting in AR largely reflects low-level simultaneous contrast, complementing higher-level accounts such as layer scissioning.
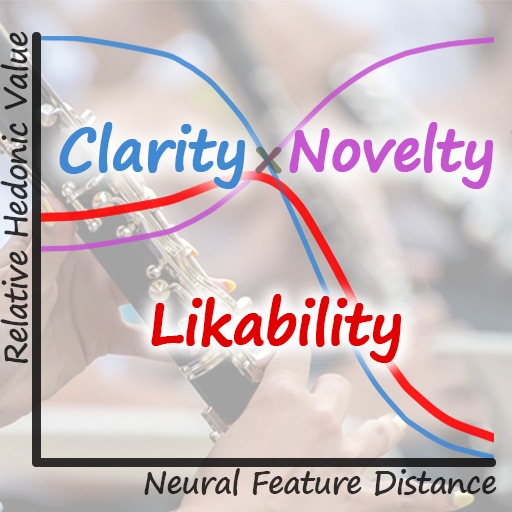
This study investigates the factors underlying the Wundt curve in graphic design based on Berlyne’s reinterpretation. The paper presents the results of a psychophysical study in which Likability, Novelty, and Clarity of manipulated flyer design images were assessed by means of magnitude estimation. To connect these measurements into a unified framework, the authors propose a model based on the (inverted U-shaped) Wundt curve, where Likability exhibits a nonmonotonic trend and is determined by the product of perceived Clarity and Novelty. To test this hypothesis, subjective evaluations were conducted using flyer design images systematically varied along a feature-distance axis defined relative to typical designs, where the feature distance was computed using EfficientNet-B0. The results showed a Wundt-curve-shaped trend with a moderate fit to the idealized curve. The findings indicate that the product of Clarity and Novelty plays an important role in determining Likability and provide a basis for refining Wundt-curve-based models.
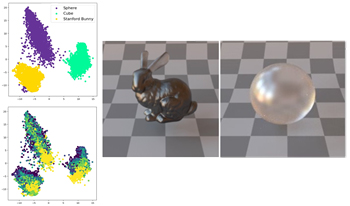
One central challenge in modeling material appearance perception is the creation of an explainable and navigable representation space. In this study, we address this by training a StyleGAN2-ADA deep generative model on a large-scale, physically based rendered dataset containing translucent and glossy objects with varying intrinsic optical parameters. The resulting latent vectors are analyzed through dimensionality reduction, and their perceptual validity is assessed via psychophysical experiments. Furthermore, we evaluate the generalization capabilities of StyleGAN2-ADA on unseen materials. We also explore inverse mapping techniques from latent vectors reduced by principal component analysis back to original optical parameters, highlighting both the potential and the limitations of generative models for explicit, parameter-based image synthesis. A comprehensive analysis provides significant insights into the latent structure of gloss and translucency perception and advances the practical application of generative models for controlled material appearance generation.
A collection of articles on remote research in cognition and perception using the Internet for the Journal of Perceptual Imaging is presented. Four original articles cover the topics of exact versus conceptual replication of cognitive effects (e.g., mental accounting), effects of facial cues on the perception of avatars, cultural influences on perceptual image and video quality assessment, and how Internet habits influence social cognition and social cognitive research. The essentials of these articles are summarized here, and their contributions are embedded within a wider view and historical perspective on remote research in cognition and perception using the Internet.
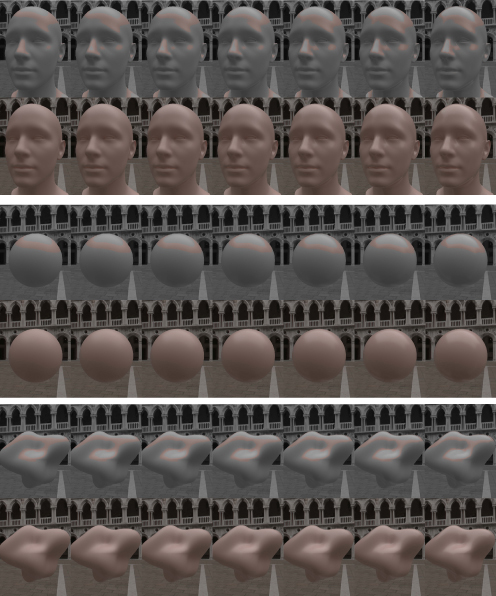
Human faces are considered an important type of stimuli integral to social interaction. Faces occupy a substantial share of digital content, and their appearance can meaningfully impact how they are perceived and evaluated. In particular, past work has shown that facial color appearance can directly influence such perceptions. However, little is known regarding the perception of facial gloss and its influence on facial skin color appearance. The current work investigates how skin roughness influences perceived facial gloss and how these in turn affect facial color appearance for 3D rendered faces. Here, “roughness” refers to a parameter of the microfacet function modeling the microscopic surface. Two psychophysical experiments were conducted to model the interaction among skin roughness, perceived facial gloss, and perceived facial color appearance using varied facial skin tones. The results indicated an exponential relationship between skin roughness and perceived facial gloss, which was consistent across different skin tones. Additionally, gloss appearance influenced the perceived lightness of faces, a pattern not observed to the same extent among non-face objects included in the experiment. We expect that these results might partially be explained by discounting specular components for surface color perception to infer color attributes and by simultaneous contrast induced by a concentrated specular highlight. The current findings provide guidance for predicting visual appearance of face and non-face objects and will be useful for gloss and color reproduction of rendered digital faces.
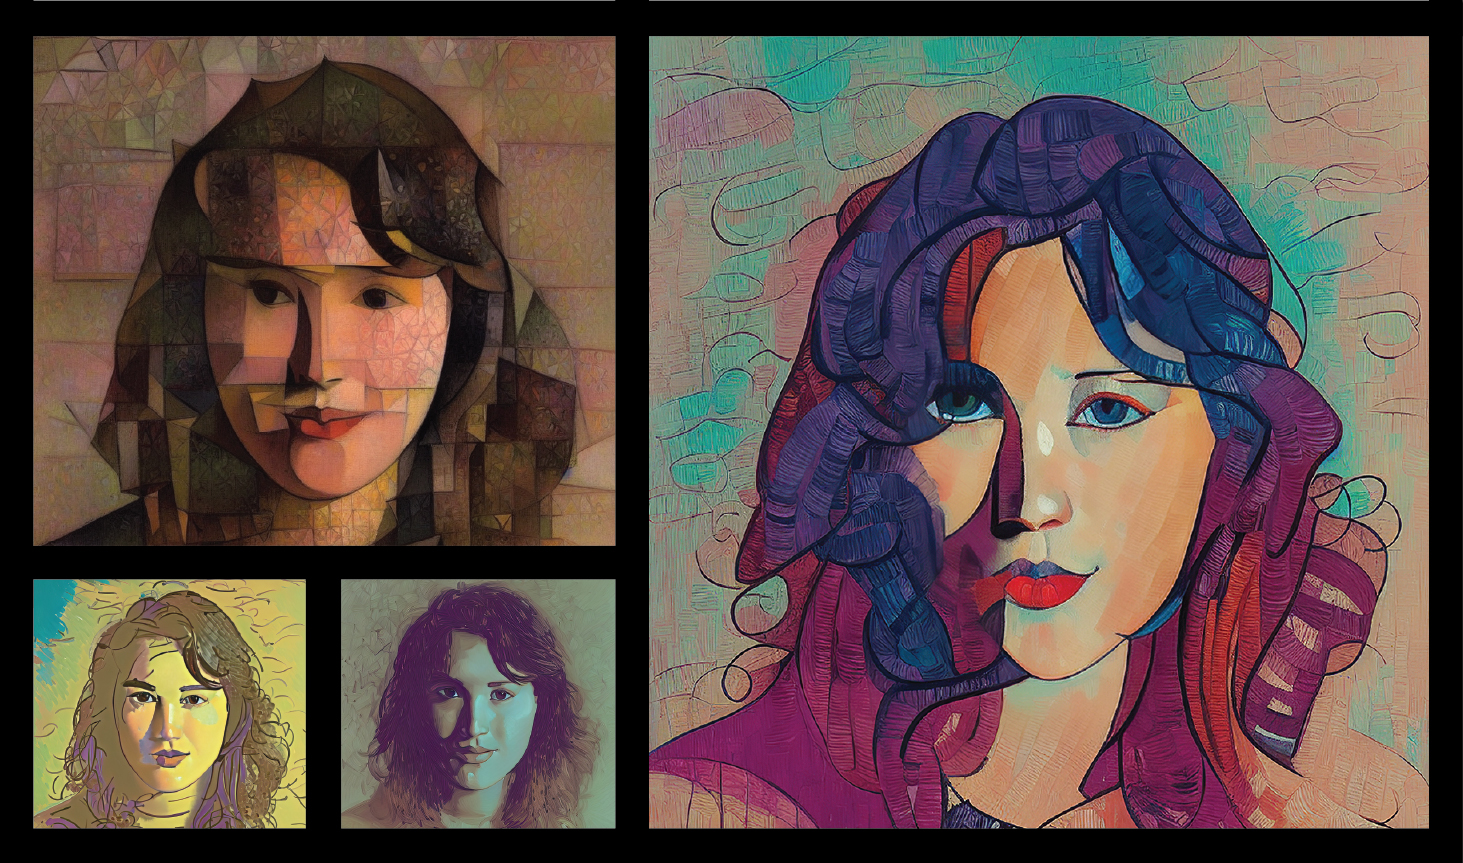
Visual content has the ability to convey and impact human emotions. It is crucial to understanding the emotions being communicated and the ways in which they are implied by the visual elements in images. This study evaluates the aesthetic emotion of portrait art generated by our Generative AI Portraiture System. Using the Visual Aesthetic Wheel of Emotion (VAWE), aesthetic responses were documented and subsequently analyzed using heatmaps and circular histograms with the aim of identifying the emotions evoked by the generated portrait art. The data from 160 participants were used to categorize and validate VAWE’s 20 emotions with selected AI portrait styles. The data were then used in a smaller self-portrait qualitative study to validate the developed prototype for an Emotionally Aware Portrait System, capable of generating a personalized stylization of a user’s self-portrait, expressing a particular aesthetic emotional state from VAWE. The findings bring forth a new vision towards blending affective computing with computational creativity and enabling generative systems with awareness in terms of the emotions they wish their output to elicit.
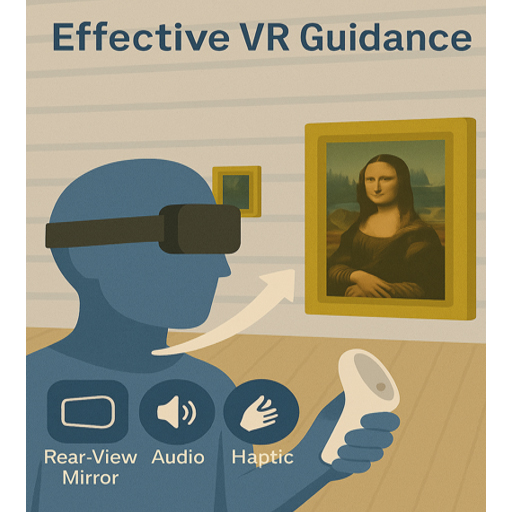
A design challenge in virtual reality (VR) is balancing users’ freedom to explore the virtual environment with the constraints of a guidance interface that focuses their attention without breaking the sense of immersion or encroaching on their freedom. In virtual exhibitions in which users may explore and engage with content freely, the design of guidance cues plays a critical role. This research explored the effectiveness of three different attention guidance cues in a scavenger-hunt-style multiple visual search task: an extended field of view through a rearview mirror (passive guidance), audio alerts (active guidance), and haptic alerts (active guidance) as well as a fourth control condition with no guidance. Participants were tasked with visually searching for seven specific paintings in a virtual rendering of the Louvre Museum. Performance was evaluated through qualitative surveys and two quantitative metrics: the frequency with which users checked the task list of seven paintings and the total time to complete the task. The results indicated that haptic and audio cues were significantly more effective at reducing the frequency of checking the task list when compared to the control condition while the rearview mirror was the least effective. Unexpectedly, none of the cues significantly reduced the task-completion time. The insights from this research provide VR designers with guidelines for constructing more responsive virtual exhibitions using seamless attentional guidance systems that enhance user experience and interaction in VR environments.
This study provides researchers, who are considering internet-based social cognitive research, with a general overview of the theoretical and methodological considerations that must be considered for implementing best practices. It covers theoretical discussions of the ways in which the internet has affected socialisation and cognitive processes (including memory and attention), the balance between ecological validity and experimental control for internet-based social cognitive research (including the effect of digital researcher presence), and group membership (including discussions of group composition, identity misrepresentation, and communication through memes). It also covers methodological discussions and best practices to account for the effects of internet use on social cognition, exploring avenues for increasing experimental control without sacrificing ecological validity, and decisions pertaining to participant recruitment issues, when recruiting from internet-based community groups.
Naturalness is a complex appearance attribute that is dependent on multiple visual appearance attributes like color, gloss, roughness, and their interaction. It impacts the perceived quality of an object and should therefore be reproduced correctly. In recent years, the use of color 3D printing technology has seen considerable growth in different fields like cultural heritage, medical, entertainment, and fashion for producing 3D objects with the correct appearance. This paper investigates the reproduction of naturalness attribute using a color 3D printing technology and the naturalness perception of the 3D printed objects. Results indicate that naturalness perception of 3D printed objects is highly subjective but is found to be objectively dependent mainly on a printed object’s surface elevation and roughness.
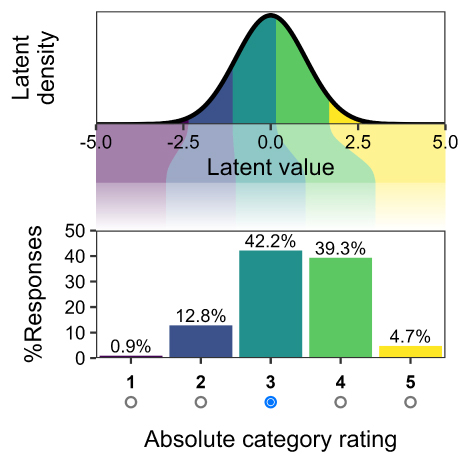
Evaluating perceptual image and video quality is crucial for multimedia technology development. This study investigated nation-based differences in quality assessment using three large-scale crowdsourced datasets (KonIQ-10k, KADID-10k, NIVD), analyzing responses from diverse countries including the US, Japan, India, Brazil, Venezuela, Russia, and Serbia. We hypothesized that cultural factors influence how observers interpret and apply rating scales like the Absolute Category Rating (ACR) and Degradation Category Rating (DCR). Our advanced statistical models, employing both frequentist and Bayesian approaches, incorporated country-specific components such as variable thresholds for rating categories and lapse rates to account for unintended errors. Our analysis revealed significant cross-cultural variations in rating behavior, particularly regarding extreme response styles. Notably, US observers showed a 35–39% higher propensity for extreme ratings compared to Japanese observers when evaluating the same video stimuli, aligning with established research on cultural differences in response styles. Furthermore, we identified distinct patterns in threshold placement for rating categories across nationalities, indicating culturally influenced variations in scale interpretation. These findings contribute to a more comprehensive understanding of image quality in a global context and have important implications for quality assessment dataset design, offering new opportunities to investigate cultural differences difficult to capture in laboratory environments.