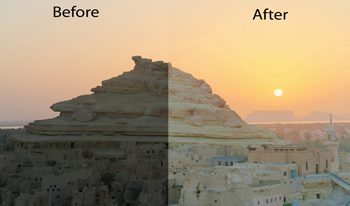
Archaeology-related images are often captured in ambient or non-ideal lighting, leading to illumination non-uniformity. It is a condition in which illumination is unevenly distributed across the image, causing some regions to appear dark while others appear bright. This effect hides details in the dark regions, reducing the usability of such images for analysis, documentation, archiving, display, and 3D modeling. Hence, a refined type-II fuzzy (RTF) algorithm is introduced to improve illumination uniformity. RTF improves uniformity by suppressing bright regions, while boosting dark regions. The experimental results demonstrate that RTF successfully performed its task, delivering better illumination harmonization in the processed images. This allowed for better perception of darkened details and confirmed that RTF can work across different illumination scenarios and scenes.
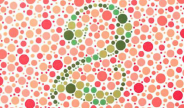
This paper describes a colour image enhancement method for those having colour-vision deficiencies. The proposed method can be divided into 3 stages. Firstly, a conversion relation between the wavelength shift (measured in nanometers) of a colour deficient observer (CDO) and the severity of colour deficiency was established. Secondly, the perceived colour gamut was built by applying the conversion relation. Finally, the original images were re-coloured by adopting a gamut mapping algorithm to map colours from the gamut of colour normal observer (CNO) to that of a CDO. Psychophysical experiments were then conducted to show the effectiveness of the method.
Diffraction X-ray images provide molecular level information in tissue under hydrated, physiological conditions at the physiologically relevant millisecond time scale. When processing diffraction x-ray images there is a need to subtract background produced during the capture process prior to making measurements. This is a non-uniform background that is strongest at the diffraction center and decays with increased distance from the center. Existing methods require careful parameter selection or assume a specific background model. In this paper we propose a novel approach for background subtraction in which we learn to subtract background based on labeled examples. The labeled examples are image pairs where in each pair one of the images has diffraction background and the second has the background removed. Using a deep convolutional neural network (CNN) we learn to map an image with background to an image without it. Experimental results demonstrate that the proposed approach is capable of learning background removal with results close to ground truth data (PSNR > 68, SSIM > 0.99) and without having to manually select background parameters.