The perceived color in optical see-through augmented reality (AR) deviates from physical additivity, but the driving factors and their interactions remain poorly understood. The authors conducted four psychophysical color-matching experiments manipulating seven factors including stimulus size, viewing mode, starting point, and presentation medium. A generalized linear mixed-effects model analysis of the coordinate-wise differences in CIECAM16-UCS space revealed stimulus size as the strongest predictor. Reducing the stimulus size—which increases the relative area of the chromatic surround—produced shifts that tended to be opposite to the background chromaticity, consistent with classical simultaneous contrast. The viewing mode and presentation medium had small effects concentrated on the blue–yellow axis, whereas the starting point produced a small procedural shift across all axes. The linear additive model showed limitations: nonlinear deviations were confined to specific targets where chromatic induction was strongest. These findings suggest that background discounting in AR largely reflects low-level simultaneous contrast, complementing higher-level accounts such as layer scissioning.
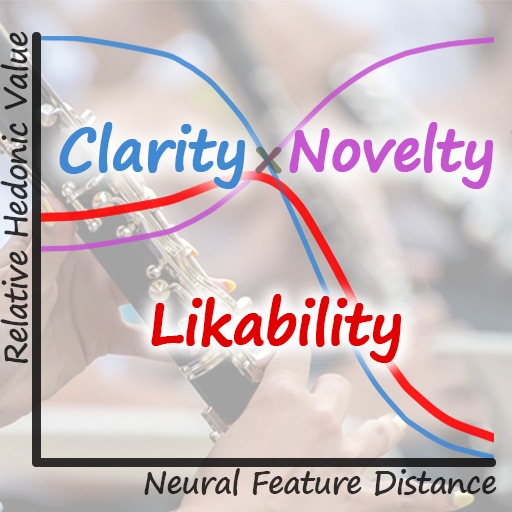
This study investigates the factors underlying the Wundt curve in graphic design based on Berlyne’s reinterpretation. The paper presents the results of a psychophysical study in which Likability, Novelty, and Clarity of manipulated flyer design images were assessed by means of magnitude estimation. To connect these measurements into a unified framework, the authors propose a model based on the (inverted U-shaped) Wundt curve, where Likability exhibits a nonmonotonic trend and is determined by the product of perceived Clarity and Novelty. To test this hypothesis, subjective evaluations were conducted using flyer design images systematically varied along a feature-distance axis defined relative to typical designs, where the feature distance was computed using EfficientNet-B0. The results showed a Wundt-curve-shaped trend with a moderate fit to the idealized curve. The findings indicate that the product of Clarity and Novelty plays an important role in determining Likability and provide a basis for refining Wundt-curve-based models.
Owing to its ability to enable precise perception of dynamic and complex environments, point cloud semantic segmentation has become a critical task for autonomously driven vehicles in recent years. However, in complex, dynamic scenes, cumulative errors pose significant challenges for existing semantic segmentation methods, limiting their accuracy and efficiency, particularly in safety-critical applications. To address these issues, this paper introduces a novel framework that balances accuracy and computational efficiency by leveraging temporal alignment. The framework effectively captures inter-frame correlations, enhances local detail information, reduces error accumulation, and maintains detailed scene features. Furthermore, by integrating LiDAR and camera data through multi-modal fusion, the framework provides complementary perspectives, significantly improving segmentation performance and robustness in dynamic environments. This method achieves competitive performance on the benchmark SemanticKITTI and nuScenes datasets, demonstrating its capability to detect occluded objects and ensure reliable perception in safety-critical scenarios. The proposed framework offers a promising solution for enhancing the robustness and reliability of autonomous driving systems in complex environments.
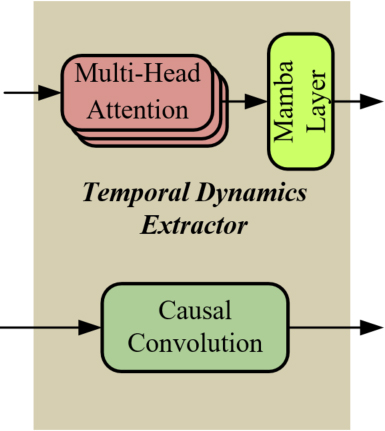
Traffic flow forecasting faces substantial challenges arising from intertwined heterogeneous temporal dynamics and complex spatial dependencies. A key difficulty lies in balancing long-term stable trends with short-term abrupt disturbances. To address these challenges, a framework named the Spatiotemporal Trend–Event Decoupling Mamba Graph Network (STEDMGN) is proposed. First, a temporal signal separation layer is constructed using a multi-scale decomposition and reconstruction mechanism to divide the raw sequence into trend and event components. This design enables dynamic pattern decoupling across multiple scales. Subsequently, a dual-frequency spatiotemporal encoder is introduced. The trend branch integrates multi-head attention with a Mamba-based state space layer to capture cross-period long-term dependencies, whereas the event branch employs causal convolution to model short-term abrupt disturbances. In the spatial dimension, trend-oriented and event-oriented graph convolutional networks are incorporated. These networks combine static priors, adaptive adjacency, and feature-driven dynamic graph structures to enhance the representation of both stable topologies and time-varying propagation. Finally, a fusion-gated decoder employs gated units and a query-driven fusion strategy to integrate the two feature types. A subsequent regression layer then generates multi-step forecasts. Extensive experiments on four public PeMS datasets demonstrate that the STEDMGN substantially outperforms state-of-the-art methods. The results provide an accurate and scalable solution for large-scale urban traffic flow forecasting.
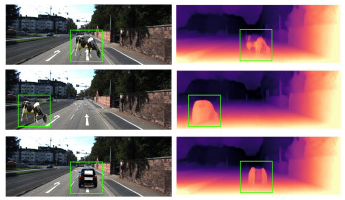
Monocular depth estimation (MDE) is a widely used technique in autonomous driving and 3D reconstruction. However, inconsistent and fragmented depth outputs can significantly undermine the reliability of MDE applications in practice. To address this issue, the authors introduce MonoHybrid, a novel self-supervised hybrid network that effectively integrates Transformer and dilated convolutional architectures. This design enables the extraction of both global and local features, enhancing the receptive field and ensuring robust and continuous depth estimation. Additionally, the authors present a new Feature Fusion Module that fuses convolutional and Transformer features, resulting in improved depth estimation performance. Through comprehensive experiments, the proposed network demonstrates notable accuracy and generalization compared to other advanced methods in the field.
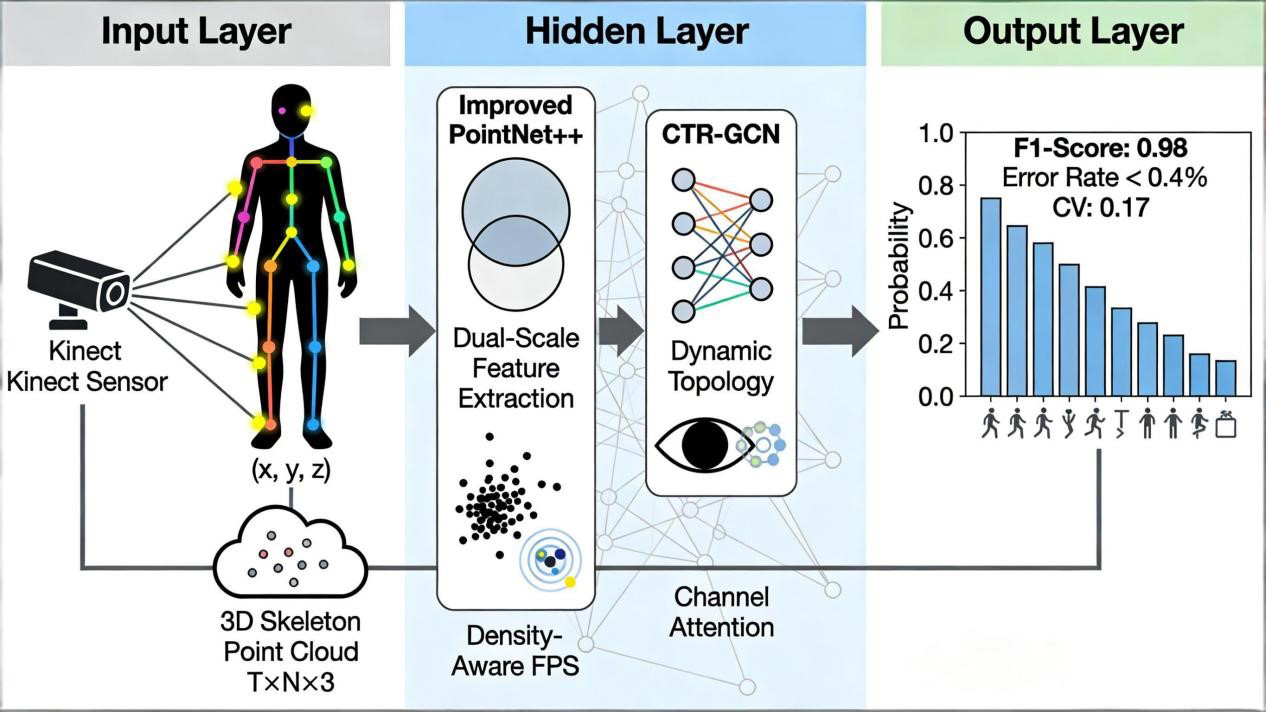
This study proposes a human dynamic behavior recognition method based on joint point extraction and deep learning algorithms. Human skeletal information is collected using a Kinect camera to obtain three-dimensional (3D) joint coordinates, completing the extraction of skeletal joint data. Based on the characteristics of bones in 3D space, processing is performed using 3D skeletal joint point cloud data. An improved PointNet++ method is employed to process the point cloud data: a dual-scale feature extraction strategy is adopted to enhance the network’s multiscale feature capture capability, and the farthest point sampling algorithm is optimized to better preserve behavioral details. Finally, a graph convolutional network approach incorporating a channel attention mechanism and graph topology optimization is used to achieve human dynamic behavior recognition based on 3D skeletons. Experimental results show that the method achieves a maximum F1 score of 0.98, a misrecognition rate below 0.4%, and a coefficient of variation of 0, demonstrating high recognition accuracy. However, the performance of this research method may be limited in complex scenes with severe occlusion or non-standard perspectives. Future work will focus on exploring multimodal data fusion and real-time optimization to further enhance its robustness and practicality in open environments.
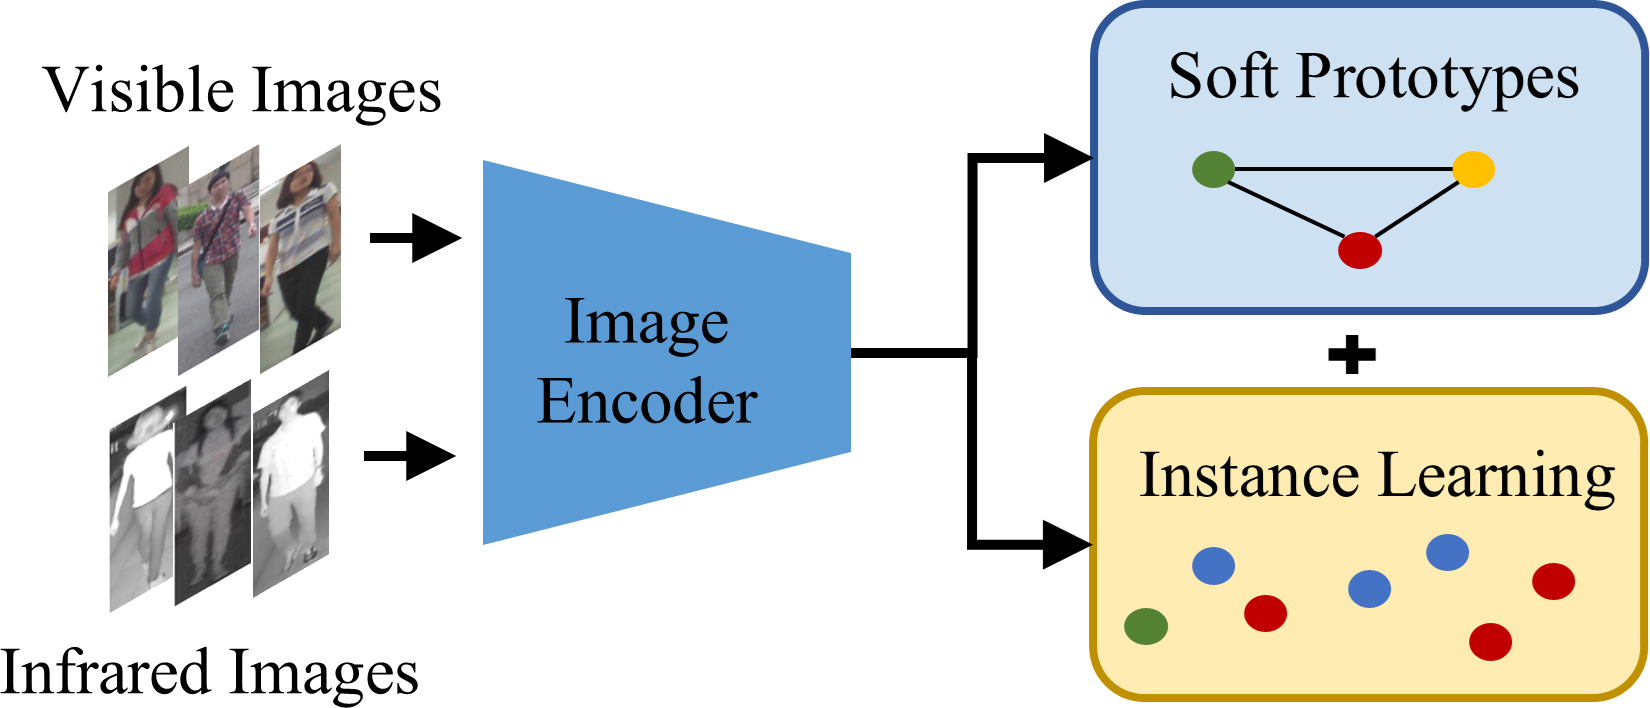
Unsupervised visible–infrared person re-identification (USVI-ReID) is a very important and challenging task in machine vision. The key challenge of USVI-ReID is to effectively mine weak class-wise supervision and establish cross-modal correspondences without using any manual annotations. In this paper, the authors propose a soft prototype contrastive learning and instance discrimination method for USVI-ReID. Specifically, soft prototype contrastive learning selects the nearest neighbors with high similarity to the soft prototypes to mine accurate information and guide the model to learn more discriminative features. On this basis, a soft weighting strategy is used to quantitatively measure the relevance of the selected soft prototypes relative to the current centroid prototype, thus further eliminating the interference of the wrong prototype in the model training. To overcome the problems of image noise and complex backgrounds in visible and infrared images, instance discriminative learning is first integrated into USVI-ReID to explore the potential similarity relationship between instances from the bottom up and learn discriminative representations. Finally, the authors propose a progressive training strategy, which enables the model to learn the similarities between instances in the early stage of training and gradually shift its attention to more discriminative categories in the later stage. Extensive experiments are conducted on two public datasets, and quantitative results prove the effectiveness of the proposed method.
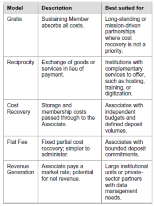
Digital preservation infrastructure remains unevenly accessible, with participation often constrained by institutional size, funding, and technical capacity. This paper presents a case study of the Academic Preservation Trust (APTrust), a community-governed digital preservation consortium, and examines how its Associate Member model functions as an incremental mechanism for broadening participation. Through sponsorship-based membership and shared governance, APTrust enables a wider range of organizations to engage in preservation activities without requiring full institutional equivalence. Drawing on early implementation experience, member census data, and the APTrust Associate Member Toolkit, this paper analyzes both the benefits and limitations of this approach, with particular attention to governance design, organizational readiness, and the distribution of risk and responsibility across member institutions.